|
00:48
leah2 left
02:25
hulk joined
02:26
kylese left
03:15
hulk left,
kylese joined
|
|||
| iwuvmika | do you know what a 'meme' is? | 03:34 | |
| [Coke] | Who are you asking? | 03:39 | |
| (me? yes) | |||
|
04:19
human-blip left
04:20
stanrifkin_ joined
04:23
stanrifkin left
04:42
mantle joined
|
|||
| japhb | .oO( Two copies of a 'me' ) |
05:40 | |
|
06:20
hurufu joined
06:57
hurufu left
06:58
hurufu joined
07:22
hurufu left
07:24
hurufu joined
07:49
leah2 joined
08:00
samebchase left
09:01
snonux left
09:15
snonux joined
09:53
Sgeo left
11:10
mantle left
11:15
mantle joined
11:24
human-blip joined
11:37
Sgeo joined
12:06
samebchase joined
12:08
Sgeo left
12:28
belluzj joined
13:06
belluzj left
|
|||
| Voldenet | meme i a funny picture you laugh at even despite laughing at it earlier? | 13:28 | |
|
13:45
tgt joined
13:50
tgt left,
tgt joined
13:51
tgt left
13:59
belluzj joined
14:15
leah2 left
14:29
leah2 joined
14:56
hurufu left,
hurufu joined
|
|||
| disbot | <antononcube> Meme is "a unit of cultural transmission, or a unit of imitation." | 15:07 | |
|
15:14
belluzj left
15:33
hurufu left
15:34
hurufu joined
|
|||
| Voldenet | I see | 15:57 | |
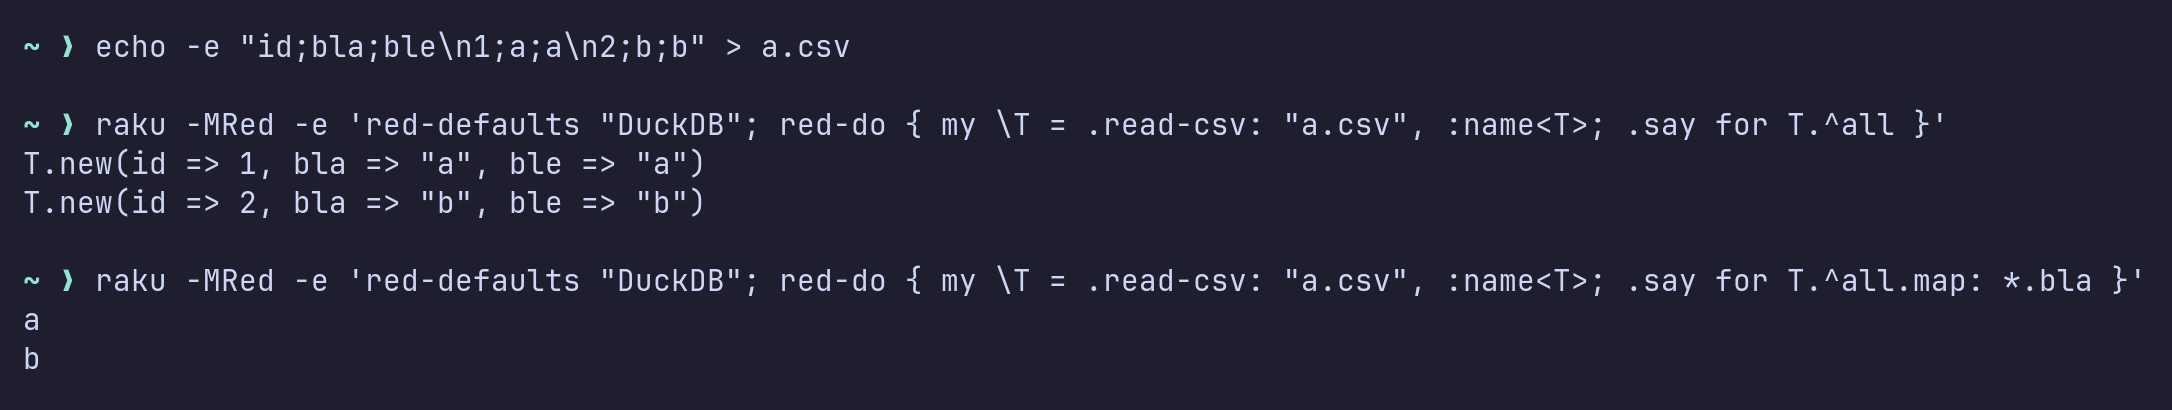
| SmokeMachine | Now we have a Red driver for DuckDB! usercontent.irccloud-cdn.com/file/.../image.png | 16:07 | |
| Voldenet | nice, how does it compare to Text::CSV? | 16:23 | |
|
16:28
hurufu left
|
|||
| SmokeMachine | idk, I have not compared... but duckdb does much more than only CSV... | 16:32 | |
| But comparing to Text::CSV, I suppose it will be much slower, because it has to create the model at read time... | 16:33 | ||
| Voldenet | I'll make some benchmarking myself because I'm curious | 16:56 | |
| I'd guess that Text::CSV would be slower | 16:57 | ||
|
17:16
swaggboi left
17:58
swaggboi joined
19:04
belluzj joined
19:17
hurufu joined
19:28
hurufu left
|
|||
| Voldenet | hmmmm, DB::DuckDB raw is very fast, but it's very tricky to use Red in this case | 19:33 | |
|
19:33
mantle left
|
|||
| Voldenet | since normally I'd use duckdb with `group by` | 19:33 | |
|
19:34
mantle joined
|
|||
| Voldenet | though doing :materialize on read-csv makes very fast queries | 19:36 | |
| it becomes 4min vs 1s comparison, which is pretty good | |||
| SmokeMachine | You can make group by with .classify | 19:51 | |
|
19:55
Sgeo joined
|
|||
| Voldenet | here's what I did (iot-sensor-100.csv has 100 lines) i.tanomi.eu/cr1eg.txt and it takes a lot of time | 19:59 | |
| …16s, which suggests a lot of work being done, potentially scanning the whole file 100 time | |||
|
20:03
mantle left
20:40
leah2 left
20:48
stanrifkin_ left
20:55
leah2 joined
|
|||
| SmokeMachine | I just added $*RED-DEBUG to that Driver (already released)... here is what that's doing: www.irccloud.com/pastebin/qRAzNtzl/ | 20:57 | |
|
21:11
belluzj left
|
|||
| Voldenet | yes, that's what I expected with that timings, good old n+1 | 21:12 | |
| I'm betting there's some form of classify I don't know | 21:28 | ||
| SmokeMachine | I’m still working on that… :) | 22:02 | |
|
22:03
vasko4535586169 left
22:04
vasko4535586169 joined
|
|||
| SmokeMachine | On my current tests, it's looking like this: www.irccloud.com/pastebin/tGfP7d72/ | 22:35 | |
| Voldenet | I wonder if there's way to express average | 23:19 | |
| but it looks a lot better, fits primary use for duckdb | 23:21 | ||
| and it looks a lot better than raw duckdb | 23:23 | ||
|
23:32
abraxxa left
|
|||